A seven-stage pipeline from book text to narrated video, in three languages
The engineering is the orchestration. Seven stages, each with the AI model picked for its one job, are kept in step by one scene number and checked after every stage, so a run of 40 episodes in English, Hindi and Gujarati could crash, resume and still finish.
One model per job
In late 2024 no model could turn a passage into a minute of watchable video. So each part of an episode went to the model best at it, and the pipeline joined them.
- Scenes
- Llama 3.3 70B
- Cuts the text into chunks of about 200 words and writes each as scenes: a title, an image prompt and the narration. It sees the chunk before, so nothing repeats. Llama 3.1 70B did this job first.
- Voice
- XTTS-v2 · MMS-TTS · Indic Parler-TTS
- English and Hindi from XTTS-v2 on the local GPU; Gujarati, which XTTS-v2 does not speak, from Meta's MMS-TTS and AI4Bharat's Indic Parler-TTS. Every file is named by scene number and language.
- Image
- Flux.1-dev, realism LoRA
- One 1920 × 1080 image per scene, with a fixed seed and one style prefix, so a series keeps one look. The three languages share it.
- Motion
- MoviePy
- Each clip runs as long as its narration: a slow zoom or pan, subtitles burned in, encoded on the GPU.
- Assembly
- ffmpeg
- Clips merge into episodes in batches, down a four-rung encode ladder from the GPU to the CPU before a clip is given up.
- Publish
- Llama 3.3 70B · Flux · YouTube Data API
- Titles, descriptions in three languages and tags, with search trends as input; a thumbnail; the upload into its language's playlist. Shorts are scheduled from the sheet.
The review sheet
Every scene lands in one shared sheet, keyed by its scene number. I read the scenes there and filled the episode column by hand; the Hindi and Gujarati columns are translation formulas. Every later stage reads its row and waits while a translation is still loading.
| Episode_no | Scene_no | Scene_title | Detailed_image_prompt | Original_story_part | …_Hindi | …_Gujarati |
|---|---|---|---|---|---|---|
| 1 | 1 | =GOOGLETRANSLATE(…, "en", "hi") | =GOOGLETRANSLATE(…, "en", "gu") | |||
| 1 | 2 | =GOOGLETRANSLATE(…, "en", "hi") | =GOOGLETRANSLATE(…, "en", "gu") | |||
| 1 | 3 | =GOOGLETRANSLATE(…, "en", "hi") | =GOOGLETRANSLATE(…, "en", "gu") | |||
| 2 | 4 | =GOOGLETRANSLATE(…, "en", "hi") | =GOOGLETRANSLATE(…, "en", "gu") |
The sheet's columns as the pipeline writes them.
Built to crash and carry on
Runs were long, and an encode can fail halfway through a batch. Every stage saves after each scene and skips what already exists, so a crashed run is started again and picks up where it broke. A check script after each stage lists what is still missing, and the stage runs again on just that.
- 12Lists the chunks still without scenes.
- 23Lists the scenes missing a language.
- 32Lists the scenes without an image.
- 42Deletes any clip whose image and narration numbers disagree.
One scene, three languages
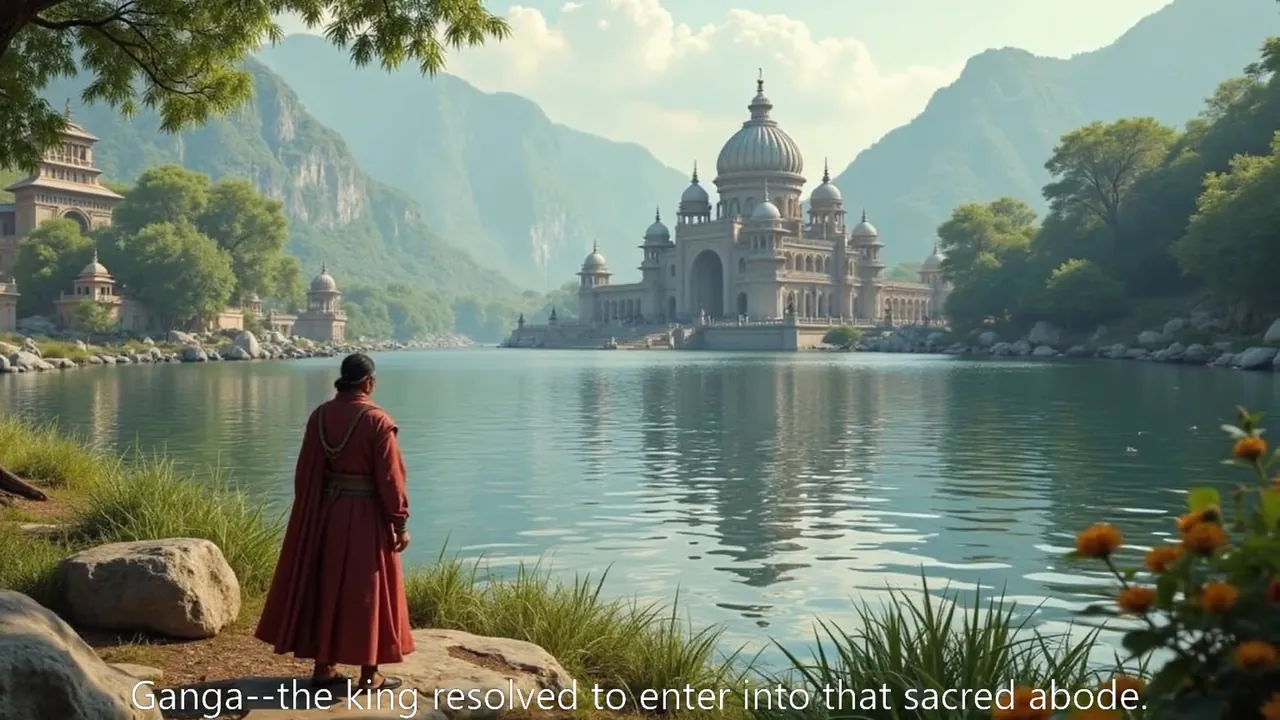
English 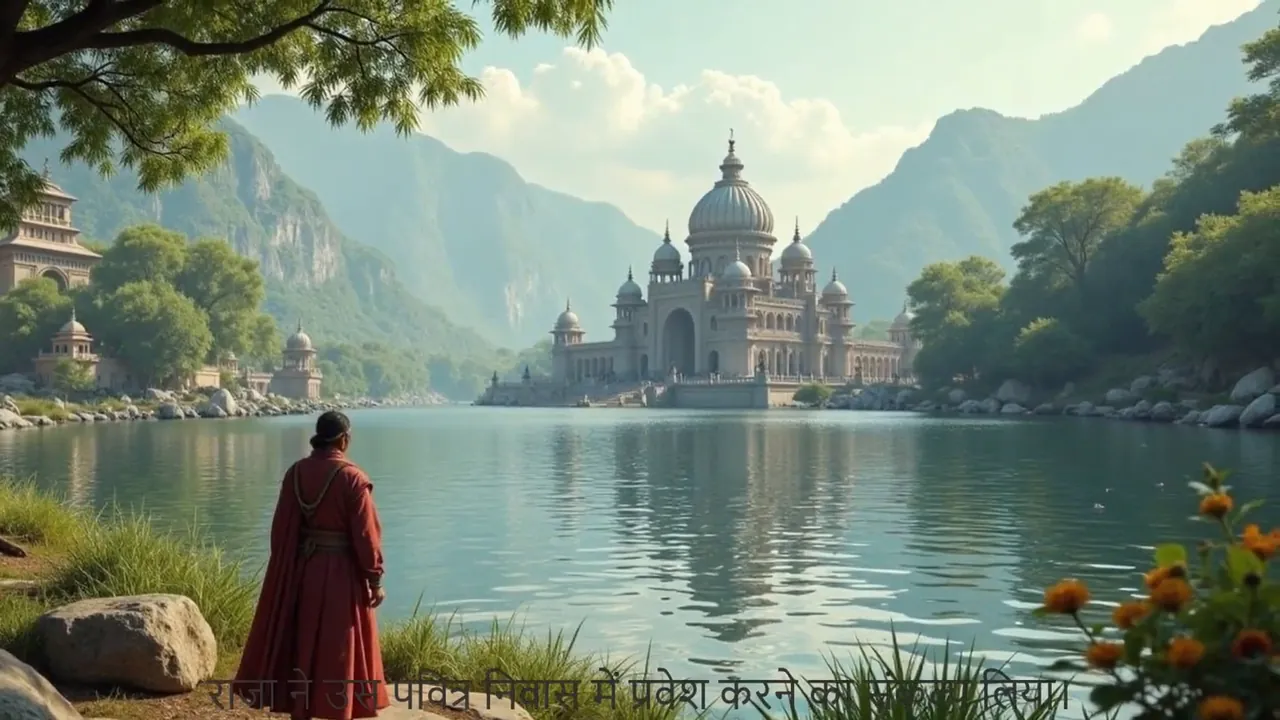
Hindi 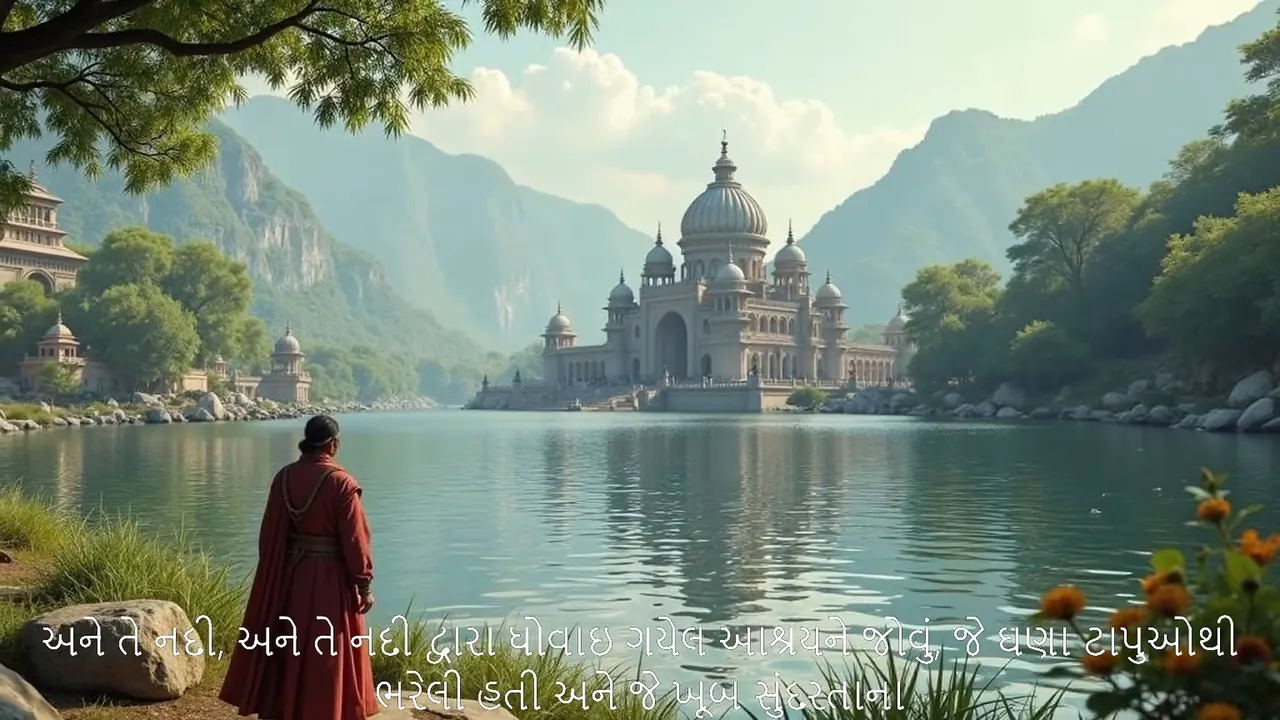
Gujarati
One image, three narrations and three sets of subtitles, keyed to one scene number.
The channel's most-watched episode
Source text: the Mahabharata, K. M. Ganguli's public-domain English translation.
Next in the Builder Lab
DeckHQ